AI SEO — Audit AI Answer Visibility Without Promising Citations
AI SEO is a 15-reference workflow for AI-answer visibility: query audits, extractable structure, crawler policy by purpose, machine-readable files, and citation-versus-recommendation analysis.
AI SEO
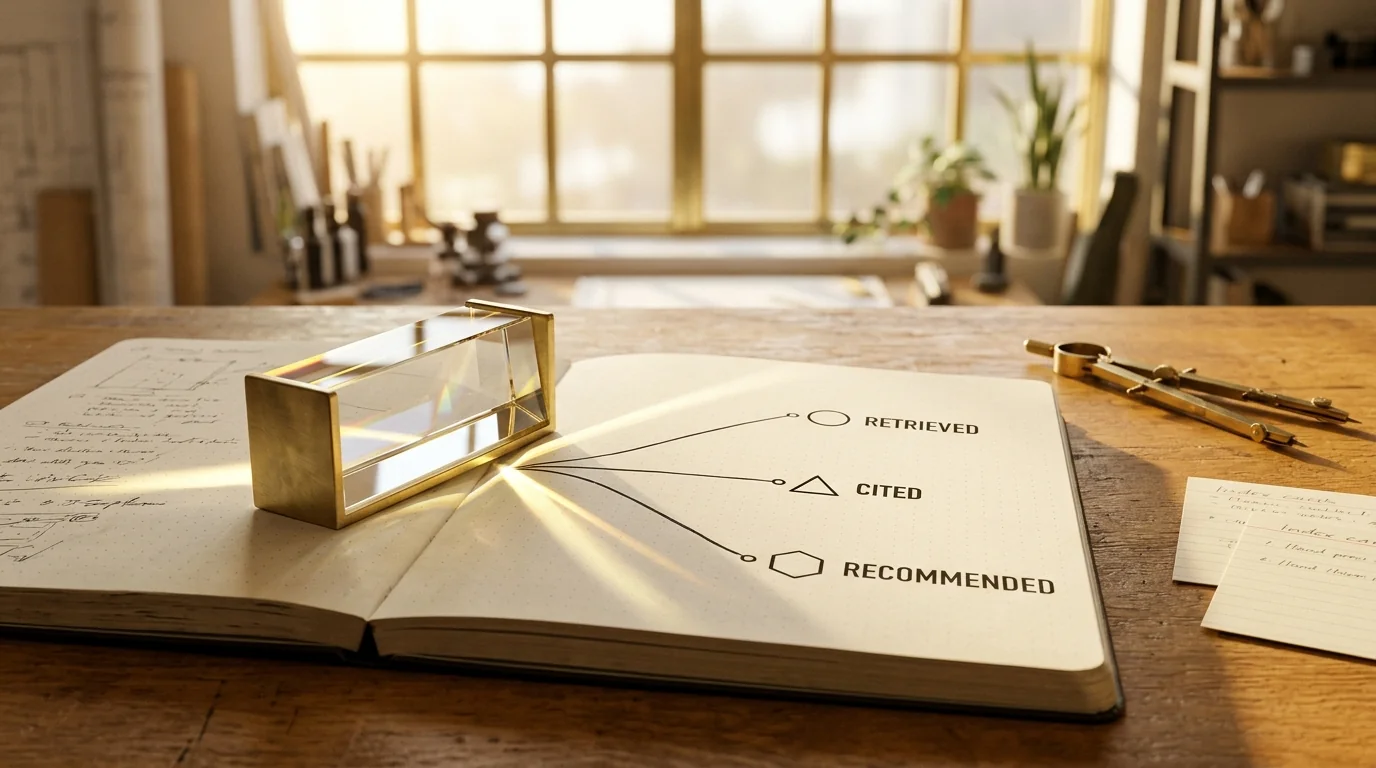
AI SEO is a marketing workflow for a specific question: when a buyer asks an assistant for a recommendation, does your content get retrieved, cited, or recommended? The skill separates those three outcomes. That separation is the most useful thing in it.
It is maintained by Corey Haines in coreyhaines31/marketingskills. The skill ships a core workflow plus 15 local reference files covering agent readiness, attribution, answer accuracy, agent defaults, citation versus recommendation, content patterns, content types, format volatility, LinkedIn, multilingual commerce, Open Knowledge Format, prompt portfolios, platform ranking factors, positioning, and YouTube citations.
Source and revision
| Field | Value |
|---|---|
| Maintainer | Corey Haines |
| Canonical source | skills/ai-seo/SKILL.md at 001fd4e |
| Revision inspected | 001fd4e08bcbdac54f55f95c1ad89533813003cf, updated 2026-10-19 |
| Access date | 2026-10-23 |
| License | MIT (LICENSE, copyright 2025 Corey Haines) |
| Install unit | skills/ai-seo/, including SKILL.md and references/ |
What the skill actually does
The skill starts with an AI visibility audit, not with content generation:
- Pick 10 to 20 revenue-relevant prompts across problem-aware, solution-aware, product-aware, and most-aware stages.
- Run each prompt across platforms such as Google AI Overviews, ChatGPT, Perplexity, Gemini, and Copilot, and record whether you were cited and which competitors were.
- Inspect citation patterns for structure, authority signals, freshness, schema, and third-party presence.
- Check extractability with a pass/fail list: clear definition, self-contained answer blocks, sourced statistics, comparison tables, FAQ, schema, author attribution, recency, heading/query match, and crawler policy.
- Audit bot access by purpose, not as one blob. Search-discovery crawlers (
OAI-SearchBot,PerplexityBot,Claude-SearchBot), user-triggered retrieval (ChatGPT-User,Claude-User,Perplexity-User), training crawlers (GPTBot,ClaudeBot), and Google'sGoogle-Extendedcontrol are different decisions.
The optimization model has three pillars:
- Structure: make passages extractable. Definitions, steps, comparison tables, pros/cons, FAQs, and cited statistics. The skill recommends 40 to 60 word answer blocks and headings phrased like queries.
- Authority: named authors, credentials, expert quotes, original data, dates, and transparent sourcing.
- Presence: be where the engine looks, including Wikipedia, Reddit, review sites, industry publications, LinkedIn, YouTube, podcasts, and Quora. The skill explicitly warns that citation mixes shift and that a single channel is fragile.
It also covers machine-readable files: /pricing.md or /pricing.txt, /llms.txt, and an optional Open Knowledge Format bundle. This is where the skill is careful: it states that Google says no special markup or files are required for AI Overviews or AI Mode, and that these files are aimed at non-Google engines and autonomous buying agents. That distinction is easy to lose when the file is summarized as an "AI SEO requirement."
The part most summaries miss
The skill separates citation from recommendation. A page can be cited as a useful source and still never appear on the buyer's shortlist. The skill says shortlist recommendations are governed by web-wide consensus: reviews, forums, analysts, press, and third-party profiles. It also warns that self-promotional "best [category]" listicles can backfire, citing a 100-query B2B study in its own reference. That study is the author's citation, not an independent measurement we ran.
The skill also separates Google's guidance from the behavior of other engines. Google says to write for people, use normal headings and paragraphs, avoid separate AI-only content, and not chunk pages into AI bait. The skill says extractable structure helps non-Google engines and does not hurt Google because it is normal content organization. That is a more defensible position than "AI SEO requires special files."
When to use it
- You need a repeatable audit of which prompts cite you and which cite competitors.
- You are deciding whether to allow or block specific AI crawlers and need the purposes separated.
- You are fixing a page that an assistant describes inaccurately.
- You are building a content plan around topics that engines fan out to, rather than one page per keyword.
- You need to explain to stakeholders why a citation is not the same as a recommendation.
When not to use it
- You want a guaranteed citation, ranking, or traffic lift. The skill itself says platforms are non-deterministic and statistics drift.
- You need a traditional technical SEO crawl, schema implementation, or link-building execution. The skill routes those to sibling skills.
- You are considering fake reviews, invented awards, or bulk Reddit/Wikipedia mentions. The skill lists those as prohibited, and they can create legal exposure.
- You cannot run prompts repeatedly. A single answer is an anecdote; the skill asks for multiple runs and a recorded sample size.
Illustrative workflow
This is a constructed example, not a run against a live site.
Task: a B2B analytics product is absent from AI answers for "best product analytics for a small SaaS team."
- Build a 15-prompt portfolio: five problem-aware, five solution-aware, three comparison, two pricing/integration. Run each three times per platform and log
cited 2/3, n=3. - Inspect the answers that cite competitors. Record the exact URLs and page formats. Do not assume the top Google result is the citation source.
- Fix the owned page that should state the missing fact: a one-sentence definition, a short "who it is for" block, a pricing table, a dated customer result, and an author box.
- Add
/pricing.mdwith the same tiers and limits as the pricing page. Keep it updated; stale pricing is worse than no file. - Decide crawler policy by purpose. Allow search discovery if you want citations; decide training separately.
- Re-run the same prompt portfolio after 30 days and compare rates, not single answers.
Expected artifacts: a prompt-by-platform citation table, a source URL list, a page-change list, and a crawler-policy note. The skill does not produce a forecast, and neither should the report.
Install
npx skills add coreyhaines31/marketingskills --skill ai-seo -a claude-code
The CLI installs the selected skill folder. For OpenCode or Codex, change the agent flag or omit it and choose interactively.
Prerequisites and footprint
| Item | Detail |
|---|---|
| Runtime | Any agent that loads SKILL.md and can read local reference files |
| Files | SKILL.md plus 15 Markdown references |
| Scripts | None referenced by the core workflow; optional tool integrations are external |
| Network | Optional. The workflow can be run manually; tool integrations are external |
| Credentials | None required by the skill. Optional Semrush, Ahrefs, Search Console, or GA4 integrations are separate accounts |
| Writes | Content and files you approve; the skill itself does not publish |
| Context cost | Core file plus selected references, loaded on demand |
The skill references commercial visibility tools (Otterly, Peec, ZipTie, LLMrefs, Profound, Ahrefs, Semrush, Omnia) but does not bundle them. Treat those as optional vendors, not prerequisites.
Limitations
- Platform behavior is volatile. The skill's own "format volatility" reference is about shifts in citation formats. Any percentage in the file is dated and platform-specific.
- AI answers are non-deterministic. The skill says to run prompts multiple times and record sample size. Most published "AI visibility" screenshots do not.
- Google and non-Google engines differ. Do not turn the skill's non-Google structure advice into a claim about Google ranking.
llms.txtis not a Google requirement. The skill says Google does not require it. Treat it as an emerging convention for other engines.- Citation is not recommendation. The skill is explicit, but the distinction is easy to drop in a executive summary.
- The studies it cites are not independent measurements by us. We did not reproduce the GEO, BrightEdge, Ahrefs, or Profound figures.
- Implementation still needs a writer and a site owner. The skill audits and advises; it does not publish or guarantee ingestion.
Verify it yourself
- Clone the repository and inspect the skill folder, including every file in
references/. - Check the reference-routing table. If a file is missing after a partial install, the skill is supposed to say so rather than pretend it read it.
- Search for remote-fetch instructions. The skill tells the agent to read bundled references, not to pull a live repository copy.
- Check the "What NOT to do" section against your own plan. Separate content, AI-bait chunking, fake mentions, and treating all crawlers as one control are the recurring failure modes.
- If you use a vendor statistic, open the cited source, note its date and sample, and label it as vendor or study data. Do not convert it into a client forecast.
- Run one prompt three times and see for yourself how much the answer moves. That is the cheapest calibration.
Review transparency
| Field | Value |
|---|---|
| Last reviewed | 2026-10-23 |
| What was inspected | Full SKILL.md, reference routing table, license, pinned commit metadata |
| What was not done | No install, no prompt runs, no visibility-tool trial, no independent verification of cited statistics |
| Reviewers | Editorial source inspection only. Not a two-model security review. |
| Re-vet trigger | Any change to the core workflow or reference set; platform or statistic updates; more than 30 days |
This page is an original guide with short attributed references to the skill. It does not reproduce the full source or the reference files.
Related
- Skills Collection — the catalog
- Humanizer — prose editing, not search optimization
- How to Vet an Agent Skill — review method
- Prompt Benchmarking — how to run repeated prompt tests
- Agent Skills — the install standard
Related Articles & Guides
 #skills
Playwright Skill — Code-First Browser Automation for Agents
lackeyjb's Playwright Skill writes and runs reusable Playwright scripts through run.js — code-first, unlike Playwright MCP control or DevTools inspection.
 #skills
UI UX Pro Max — Searchable Design Intelligence for Agents
UI UX Pro Max packages seven design skills, a local search corpus and a CLI. The core is MIT; logo/CIP and extended asset generation sit behind a paid Premium tier.
 #skills
Browser Testing with DevTools — Real Chrome Evidence Through MCP
Addy Osmani's browser-testing skill connects an agent to Chrome DevTools MCP for DOM inspection, console logs, network traces, screenshots, and accessibility checks, with explicit profile-isolation and untrusted-content rules.